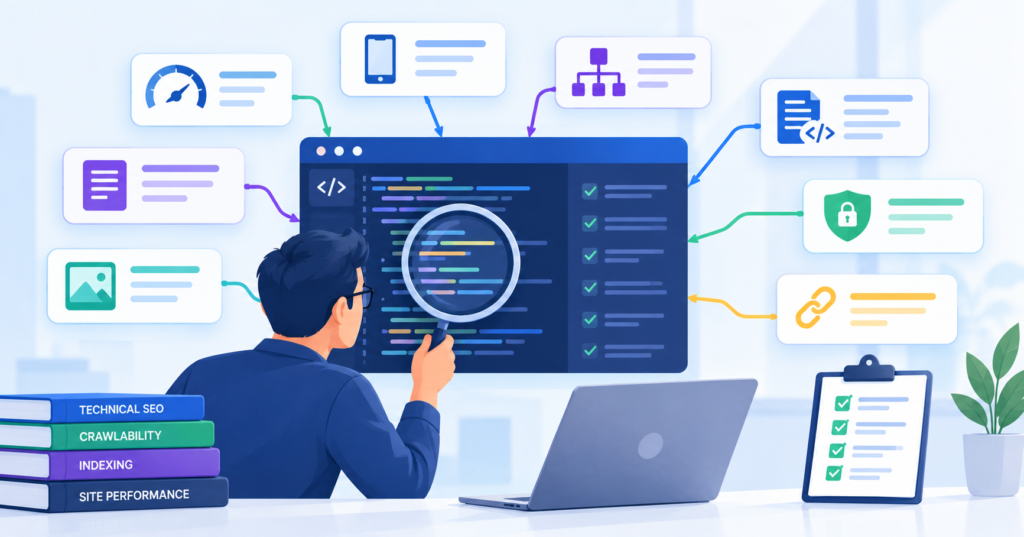
A real technical SEO audit tells you what Google’s crawler is actually doing on your site, not just what a scanning tool assumes it’s doing. Most audits stop at the surface: a crawl report, a list of broken links, a Core Web Vitals score, and a PDF. That surface layer isn’t wrong. It’s just half the job.
The differentiator isn’t the checklist. It’s how far down the list an agency is willing to go.
The Surface Layer Almost Everyone Covers
Any competent audit tool will catch these, and any firm running one should confirm them.
- Broken links and 404 errors
- Missing or duplicate title tags and meta descriptions
- XML sitemap present and submitted in Search Console
- Basic mobile-friendliness
- HTTPS and certificate validity
- Obvious robots.txt blocks
None of this is bad work. It’s just automatable, and automatable work is where a lot of “audits” quietly stop.
Where a Genuinely Thorough Audit Keeps Going
Page Indexing Analysis, Not Just Crawlability
A crawl tool shows you what should be crawlable. Server log files show what Googlebot actually requested, how often, and which pages it ignores. This is the difference between assuming Google reaches your key pages and confirming it. Log analysis surfaces crawl budget waste, pages being crawled at volume for no reason, and important pages Google rarely touches, none of which show up in a standard crawl report.
JavaScript Rendering Checks
Google renders JavaScript in a two-wave process that can delay indexing, and AI retrieval bots are often worse at rendering JavaScript than Googlebot is. If a page’s real content only appears after client-side rendering, a surface audit that just checks the raw HTML will miss that the content is effectively invisible to the systems reading it.
Crawl Budget and Crawl Traps
On any site above roughly 1,000 pages, faceted navigation, parameter URLs, and calendar widgets can generate near-infinite variations that eat crawl budget Google should be spending on pages that matter. Spotting this means comparing what’s in the sitemap against what a crawler actually discovers, not accepting the sitemap at face value.
Orphan Pages
A page with zero internal links pointing to it is effectively invisible to crawlers, no matter how good the content is. Finding orphan pages means cross-referencing a full site crawl against the sitemap, a step a lot of quick audits leave out entirely.
Canonical and Indexation Conflicts
Canonical tags pointing to the wrong URL, or applied inconsistently across templates, can quietly split authority between pages that should be competing as one. A thorough audit checks Search Console’s “Discovered but not indexed” and “Crawled but not indexed” reports, since both are common symptoms of crawl budget problems or quality signals Google didn’t like.
AI and Structured Data Readiness
Structured data is no longer a nice-to-have layer applied after everything else is clean. It’s part of how AI Overviews and other AI search tools decide what to cite. An audit that checks for schema presence but never validates it against Google’s Rich Results Test, or never asks whether AI crawlers can actually parse the page’s content, is only checking half the picture.
Why the Gap Matters
The pattern shows up the same way every time: an agency delivers a polished report with crawl depth charts and a Core Web Vitals score, the client is satisfied, and six months later organic traffic is flat with nobody able to explain why. The answer usually lives in the layers a surface audit never opened: what the server logs actually show, what the crawl budget is being wasted on, and which pages nobody can find.
A prioritized roadmap sitting in a spreadsheet for six months produces zero ranking improvement. The value of an audit isn’t the list. It’s whether anyone follows through on fixing what the list found, starting with crawlability and indexation before speed and content work, since neither of the latter matters if Google can’t reach the page in the first place (W3era).
A Quick Way to Tell the Difference
Ask a prospective agency these three questions before signing anything:
- Do you review server log files, or only a simulated crawl?
- How do you check whether my JavaScript-rendered content is actually visible to Google and to AI crawlers?
- What’s your process for finding orphan pages?
If the answer to any of these is vague, you’re likely looking at a surface audit wearing a thorough one’s price tag.
Frequently Asked Questions
What is the difference between a technical SEO audit and a surface-level SEO check?
A surface check confirms the basics: broken links, meta tags, sitemap presence. A technical audit goes further, reviewing server logs, crawl budget, JavaScript rendering, and orphan pages to confirm what search engines and AI crawlers actually see, not just what a scanning tool assumes.
How often should a law firm run a technical SEO audit?
A full audit after any major site change (a redesign, CMS change, or migration) plus at least once a year otherwise. Core Web Vitals and crawl errors are worth checking more frequently between full audits.
Why does log file analysis matter if my crawl tool already found issues?
A crawl tool shows what’s technically crawlable. Log files show what Googlebot has actually been requesting on your real server, which is often a different picture, especially on larger sites (Search Engine Journal via Google’s documentation on Googlebot behavior).
Can a site be technically clean and still perform poorly in AI search?
Yes. Structured data and content that’s readable without JavaScript are what AI systems rely on to cite a page accurately. A technically clean site that machines can’t interpret is still an opportunity missed.